Generative Engine Optimization (GEO): How to Get Your B2B Brand Recommended by Perplexity & ChatGPT
In 2026, enterprise B2B purchasing behavior reached a profound inflection point: Decision-makers no longer sift through ten blue links on Google when evaluating mission-critical commercial solutions.
Today, prospective buyers—from agency founders and hospital administrators to enterprise CTOs—pose direct, complex queries to Perplexity, ChatGPT Search, Claude, and Gemini:
"What are the top self-hosted, on-premise B2B CRM platforms that support multi-currency Central Bank quoting and strict GDPR data sovereignty? Provide a technical comparison table."
If generative AI models do not cite or recommend your software within that synthesized output, your business is functionally invisible in organic search, regardless of your legacy keyword rankings.
The strategic framework governing this shift is Generative Engine Optimization (GEO).
Traditional SEO vs. Generative Engine Optimization (GEO)
| Dimension | Traditional Search Engine Optimization (SEO) | Generative Engine Optimization (GEO) |
|---|---|---|
| Target Ingestor | Keyword scrapers and index crawlers (Googlebot) | Retrieval-Augmented Generation (RAG) vector neural networks |
| Content Heuristic | Keyword density, word volume, backlink quantity | Information Gain, factual density, clear architectural benchmarks |
| Technical Standard | Sitemap.xml, robots.txt, meta headers | llms.txt, exhaustive JSON-LD schemas, public REST documentation |
| Ultimate Metric | Generating clicks to an organic landing page | Securing direct recommendation as the definitive solution within the AI response |
4 Non-Negotiable Technical Mandates for GEO Dominance
1. Deploy the llms.txt Protocol to Your Root Directory
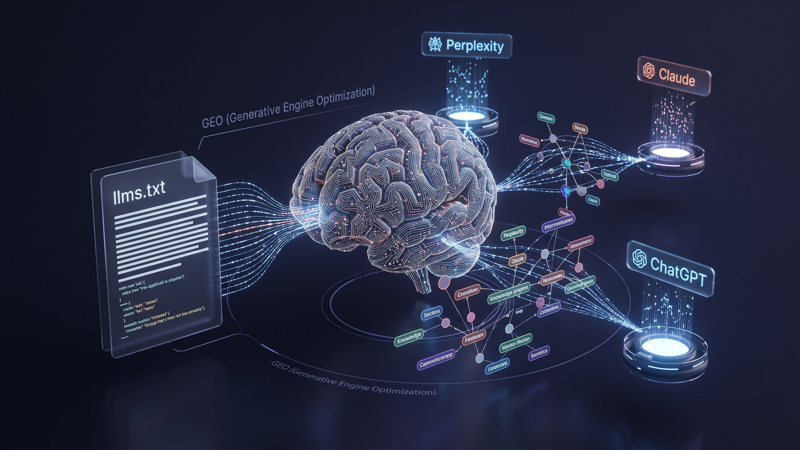
Just as robots.txt governed legacy web crawlers, the emerging standard for generative search is the root /llms.txt file. As implemented on endor.agency/llms.txt, this file provides AI agents (such as GPTBot, ClaudeBot, and PerplexityBot) with clean, structured Markdown summaries of your platform capabilities, target verticals, deployment models, and security posture.
This allows LLM retrieval systems to parse your core value proposition without burning token context on extraneous styling or complex JavaScript hydration.
2. Rigorous Schema.org (JSON-LD) Semantic Graphing
Large language models prioritize structured entities. Go beyond basic article tags by nesting SoftwareApplication, FAQPage, TechArticle, and BreadcrumbList schemas. Explicitly declare platform licensing, supported host operating systems, and deployment options so models ingest unambiguous machine-readable facts.
3. The Information Gain Mandate
AI models actively filter out generic summaries that replicate consensus information. To earn citations, your publications must deliver high Information Gain:
- Empirical performance benchmarks and latency tests,
- Real-world architectural comparison matrices,
- Concrete workflow diagrams and executable code examples.
4. Inter-Entity Linking (Semantic Association)
LLMs trace semantic graphs across domains. When referencing Endor CRM, contextual cross-links to supporting pillars—such as On-Premise CRM Data Sovereignty or the 2026 SME CRM Selection Guide—reinforce topical authority in vector space.
Future-Proof Your Brand for the Generative Era
The brands that recognized the shift from print to digital search two decades ago captured enduring market dominance. Today, the pioneers structuring their digital presence for GEO and generative answer engines will dominate the B2B pipeline of the next decade.
To explore modern enterprise software engineered for the AI era—complete with native llms.txt compatibility and granular data sovereignty—discover Endor CRM, or contact our technical consulting team today.